AI Business Solutions
GitHub brings repeatable agent checks into Copilot with Evals preview
An AI assistant can produce a convincing demonstration while still missing a detail that matters in everyday work. When a team changes its instructions or tools, keeping a small set of repeatable tasks can make the resulting behavior easier to inspect.
What GitHub released
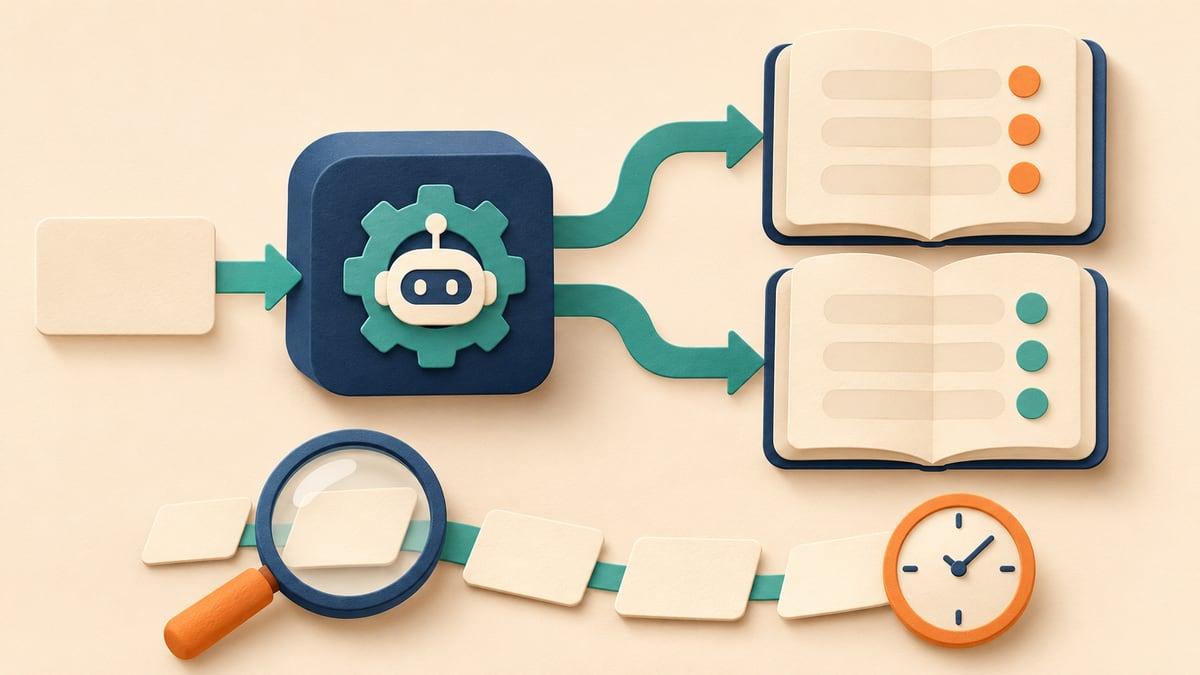
GitHub announced Copilot Evals in public preview on November 17 for Copilot Individual, Business and Enterprise plans. The feature supports evaluations of skills, custom agents and Model Context Protocol tools in a Copilot setup. GitHub describes creating a test, running checks and comparing saved runs before and after a customization change.
The announcement identifies Vally as the evaluation engine and says each run requires approval before it starts. This is a preview release, not evidence of a particular company's productivity improvement or an assurance that a customized agent will behave correctly in every situation.
Check the work and the path taken
Microsoft's Vally documentation separates the task input, the component being tested, the recorded sequence of actions, the checks applied and the resulting score. It describes a trace that includes turns, tool calls and token use. That structure gives a reviewer more to examine than the final answer alone.
Consider a hypothetical operations team using an agent to draft a release note from supplied change notes. An acceptable draft might need to distinguish completed work from deferred work and preserve the verification evidence that was actually supplied. A fluent paragraph would not, by itself, establish that those conditions were met. This is an illustrative business task, not an OrangeHat customer case or a reported test result.
Make the expected behavior inspectable
GitHub's documentation demonstrates an illustrative workflow for a pull-request-description skill, including a case where deferred work is incorrectly presented as shipped. The example is labeled illustrative; its displayed outcome should not be treated as an independent benchmark.
For the hypothetical operations team, a small evaluation brief could make the decision criteria concrete before changing the agent. These are suggested review questions rather than product guarantees.
- Inputs: Which source notes may the agent use, and which facts are absent?
- Output: Which distinctions must the draft preserve, such as completed versus planned work?
- Actions: Which files or tools are within scope, and which actions would be unexpected?
- Comparison: What changed between runs, and what evidence would justify keeping that change?
Separate evaluation quality from a passing score
A pass is meaningful in relation to the checks and cases selected. For the operations example, a team could include a straightforward task, a task with missing verification and a task containing contradictory notes. Keeping those inputs and criteria stable would make a before-and-after review easier to interpret. It would not establish coverage of every future request.
The Copilot Evals documentation also shows an approval step that discloses possible token or credit usage and the ability of tools to change files or access the network. That is a reason to review an evaluation's execution scope as well as its scoring rules. This report does not install or run the preview, and presents no measured cost, speed or accuracy result.
For a business decision, the practical question is whether the selected cases expose failures that matter to the intended workflow. A larger scorecard without representative cases can still leave that question unanswered.
Sources
What to watch
Keep the comparison tied to a business task
A useful evaluation record connects the task, expected behavior, recorded actions and result. The new preview offers a way to organize that comparison; the team still has to decide whether its examples and checks represent the work it intends to rely on.