IT Infrastructure
Cloudflare expands page snapshots with PDFs, links and structured data
A supplier-page review may need a readable copy, a list of reference links and a few fields for a spreadsheet. Separate browser visits complicate that record when the page changes between visits. Cloudflare's latest update brings more of those outputs into one request.
What changed on November 19
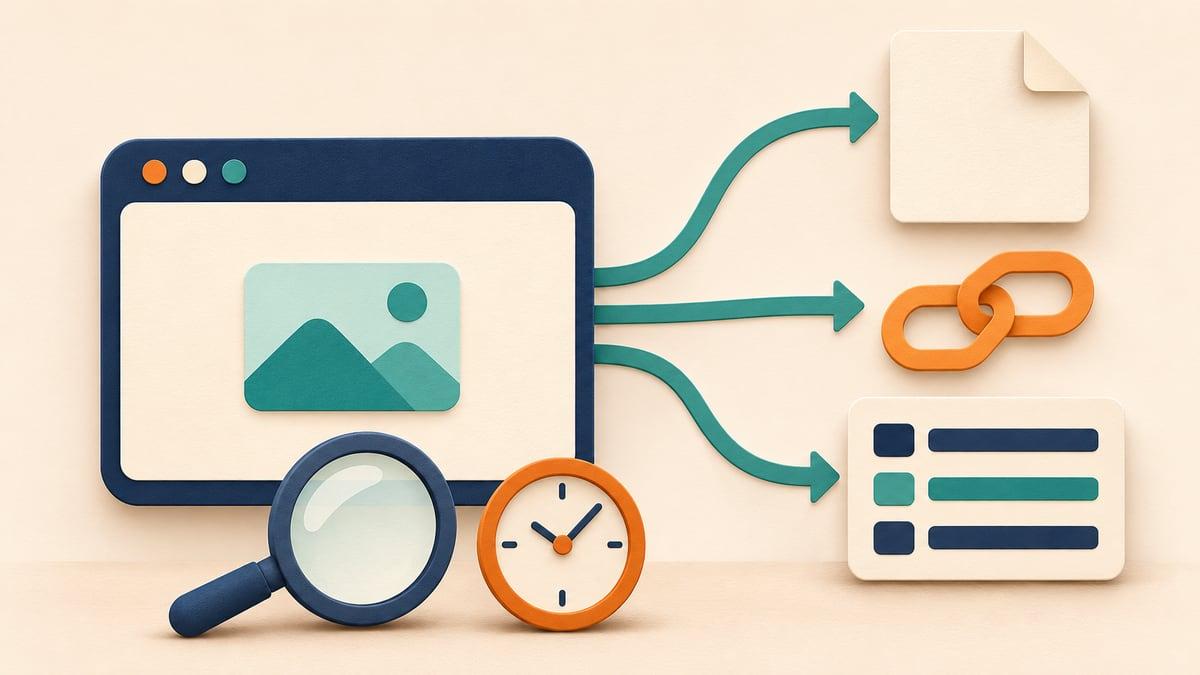
Cloudflare announced four additional Browser Run /snapshot formats: PDF, links, scraped elements and extracted JSON. These join existing page representations such as HTML and screenshots, allowing more outputs to come from a single page load.
The useful change is in workflow assembly. A team that needs both a readable archive and selected page data can request them together. The announcement does not establish a particular business's time savings, accuracy or operating cost, and this report includes no benchmark or customer implementation.
Capture order belongs in the record
Cloudflare says formats are captured in a fixed order, rather than the order supplied by the caller. PDF printing happens last because print handlers can change a page. The documentation also warns that a live page can change between captures.
For a hypothetical procurement analyst reviewing a supplier's public product page, that means the readable document, extracted fields and links should be treated as related observations with a known capture process. If a value differs between outputs, the discrepancy needs review before it is copied into a purchasing record. This is an example of a review process, not a finding about any supplier.
Treat missing data and request failure separately
The /snapshot reference requires at least two distinct formats; a single output belongs on its corresponding endpoint. It also says that failure of any requested format fails the whole request. For JSON captures, navigation, captures, retries and the AI operation share one timeout budget.
A downstream workflow can make those boundaries visible. A failed capture should not silently become an empty product list, and an unavailable field should not automatically become a confirmed negative answer. Those are proposed acceptance checks, not guarantees supplied by the endpoint.
- Record which outputs were requested and whether the request completed before accepting any extracted values.
- Keep a clear exception state for a missing field or disagreement between the readable page and the structured result.
- Preserve the source URL, capture time and extraction instructions so another reviewer can understand what was examined.
A structured result still needs a content check
Cloudflare's JSON documentation describes a prompt as extraction guidance and a JSON Schema as the expected output structure. It notes that JavaScript-heavy pages can produce empty or incomplete results when content has not finished rendering. It also documents schema-shaped placeholder results for JSON Quick Actions under local wrangler dev unless remote browser binding mode is used.
For the procurement example, checking that a returned object has a price field answers a structural question. Confirming the currency, product variant and visible source value is a separate content check. A sensible trial would include a known complete page, a page missing an expected field and a page whose content changes after initial load, with the expected handling written down in advance.
The JSON format uses Workers AI and incurs its usage; the snapshot documentation distinguishes this from a PDF, links and scraped-elements combination that does not use Workers AI. A workflow evaluation therefore needs to identify the requested formats and services rather than assume every snapshot has the same resource profile.
Sources
What to watch
Make the capture record useful to the next reviewer
A practical record identifies the source, time, requested outputs and checks still outstanding. The new formats can support that record; the decision to rely on an extracted value still needs evidence from the captured material.